


Junhua (Harry) Huang
I'm a master's student in Electrical and Computer Engineering at UCLA. I do research at VAIL with Prof. Bolei Zhou.
I work on robot learning with real hardware. So far that has meant a power wheelchair, a quadruped with a robot arm on its back, and Meta Aria glasses.
I'm looking for a full-time role or a PhD position in robot learning and robotics, starting in 2027.
Work
-

ChairNav
We taught a power wheelchair to drive long outdoor routes using a delivery robot's driving data and its rider's corrections. I built the cross-embodiment data pipeline and worked on the chair's hardware and onboard software.
-

Cue the Flow
We steer flow-matching policies for delivery tasks in the open world. I integrated the robot arm on a quadruped and deployed the models on it, with a Jetson handling the camera images and sending them to remote inference.
-

Picking a wheelchair goal with your eyes
I'm working on letting a rider pick the wheelchair's goal with Meta Aria Gen 2 glasses: look at a spot on the floor, then pinch. So far I've only tested it offline, with one wearer.
-
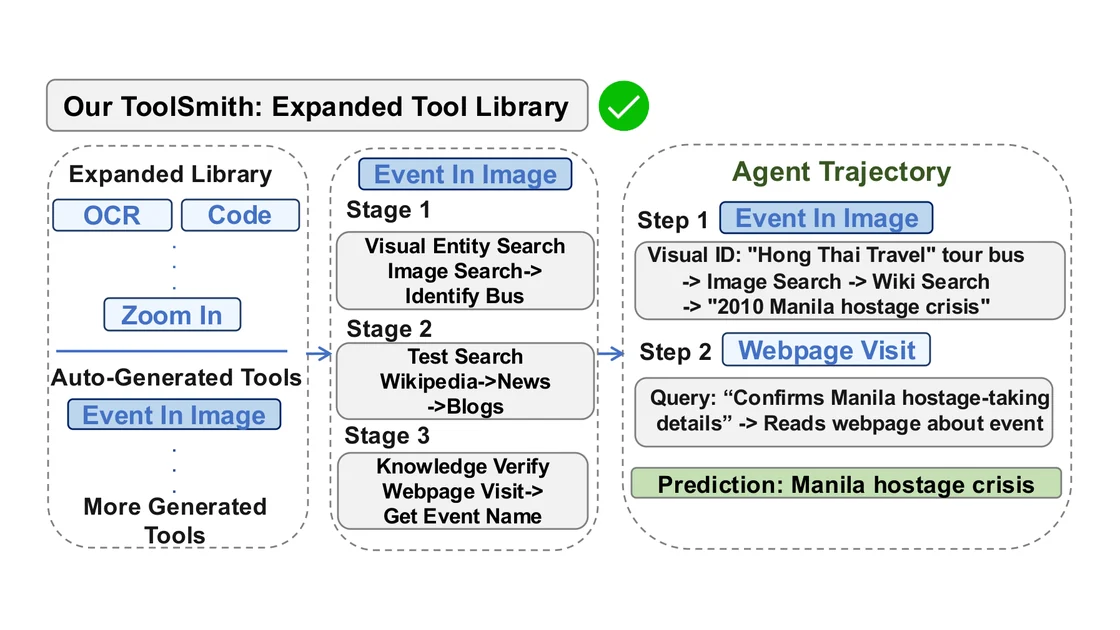
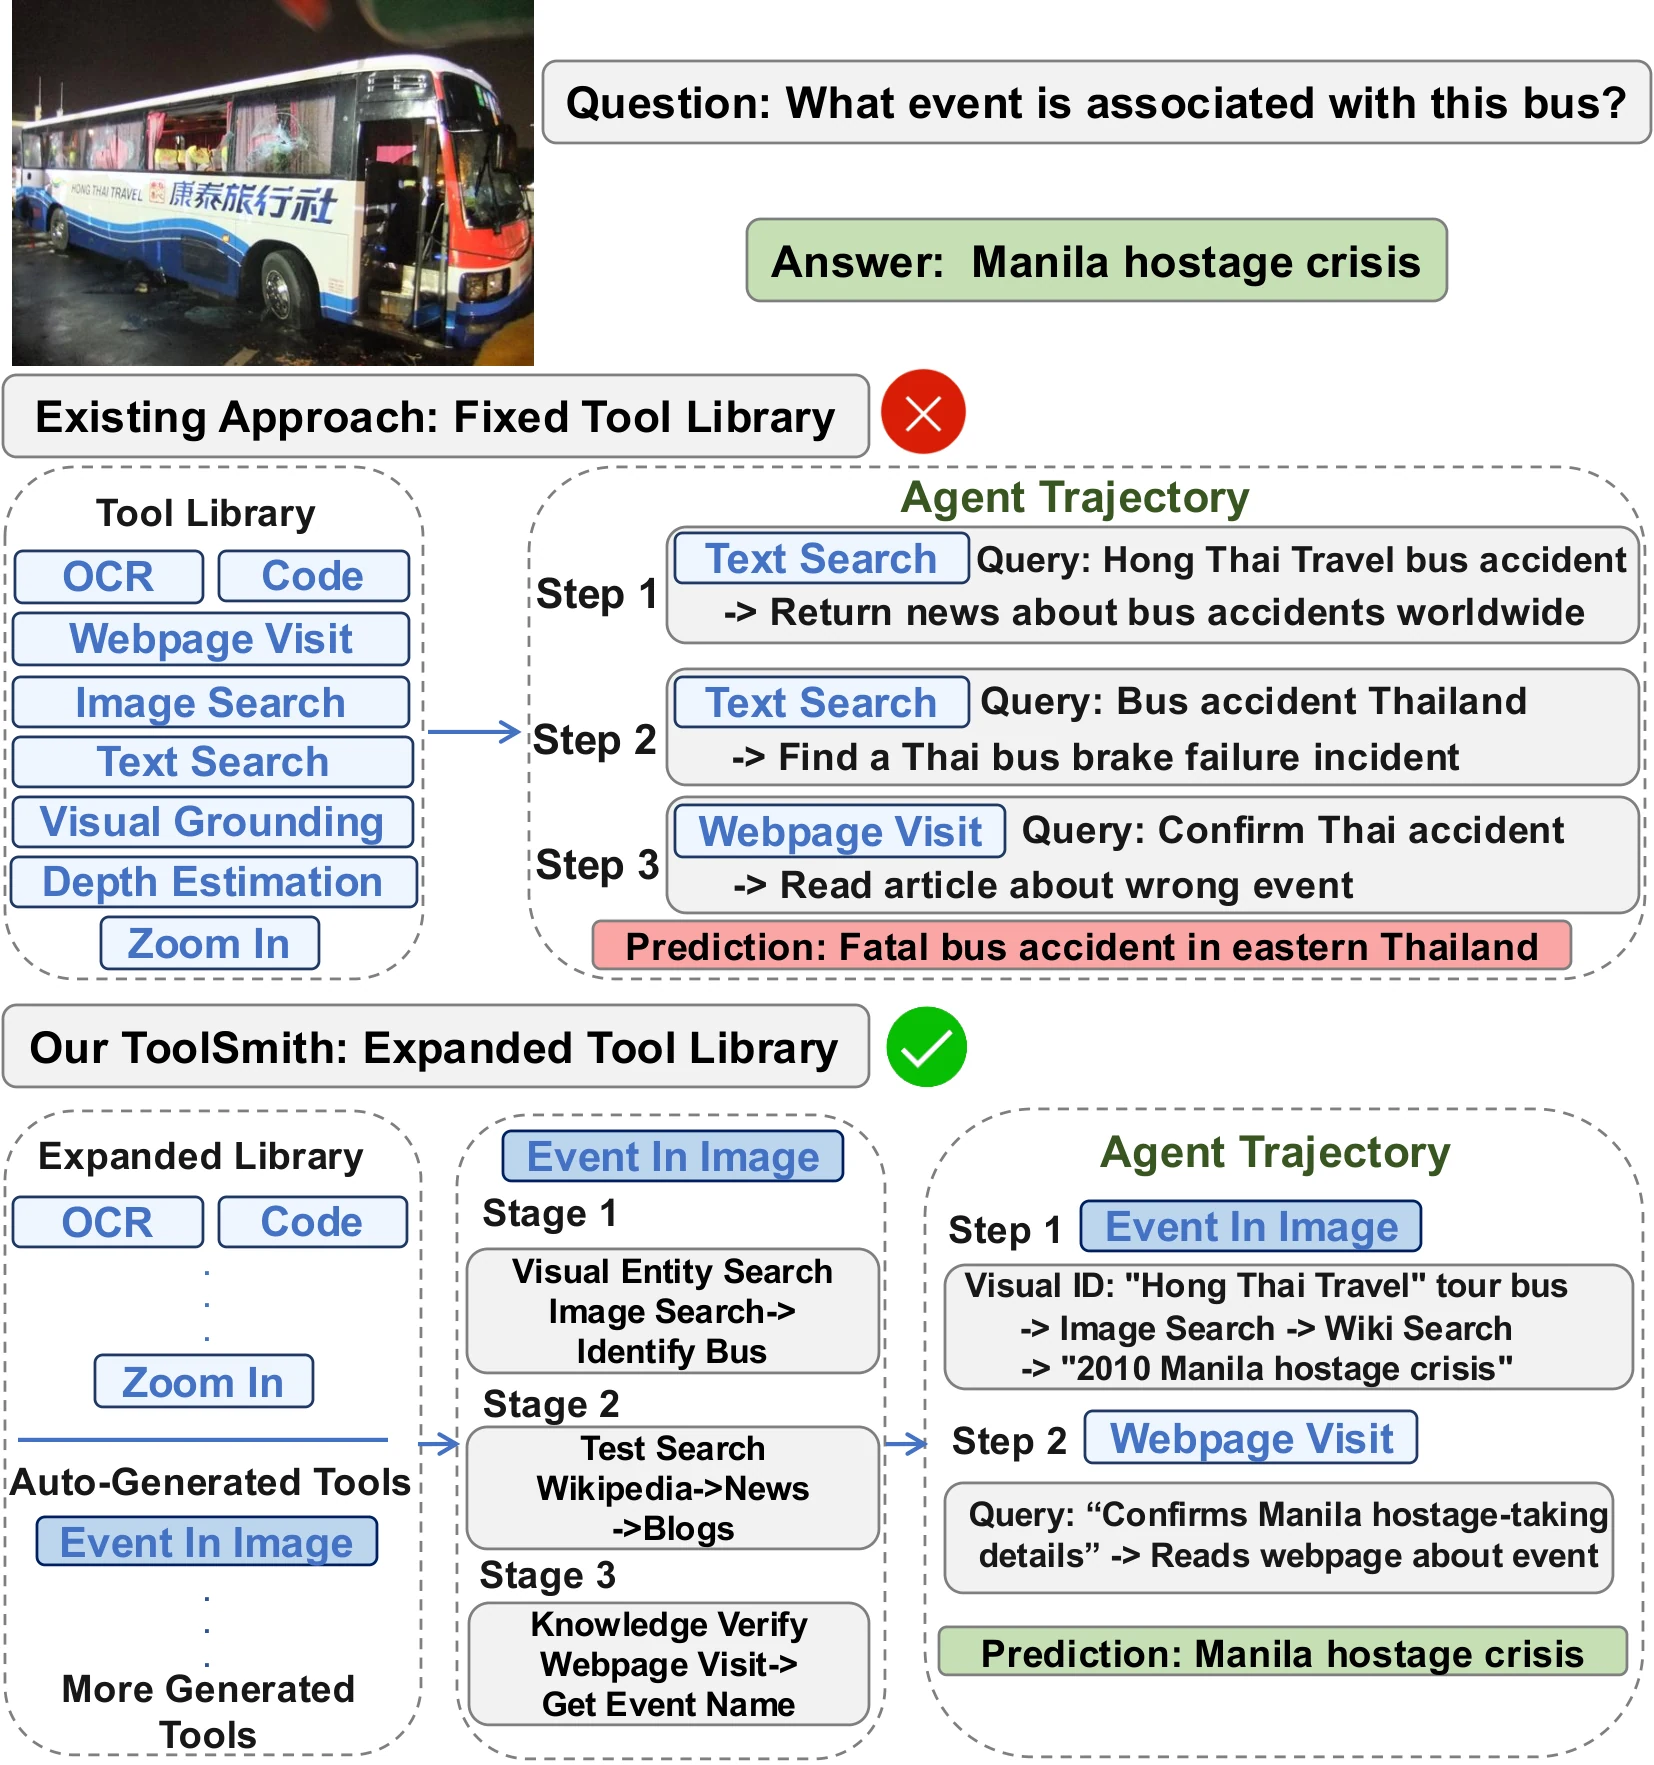
ToolSmith
I helped build a framework that writes and checks reusable Python tools for multimodal search agents, based on their failed runs.
Findings of EMNLP 2026 Project
-
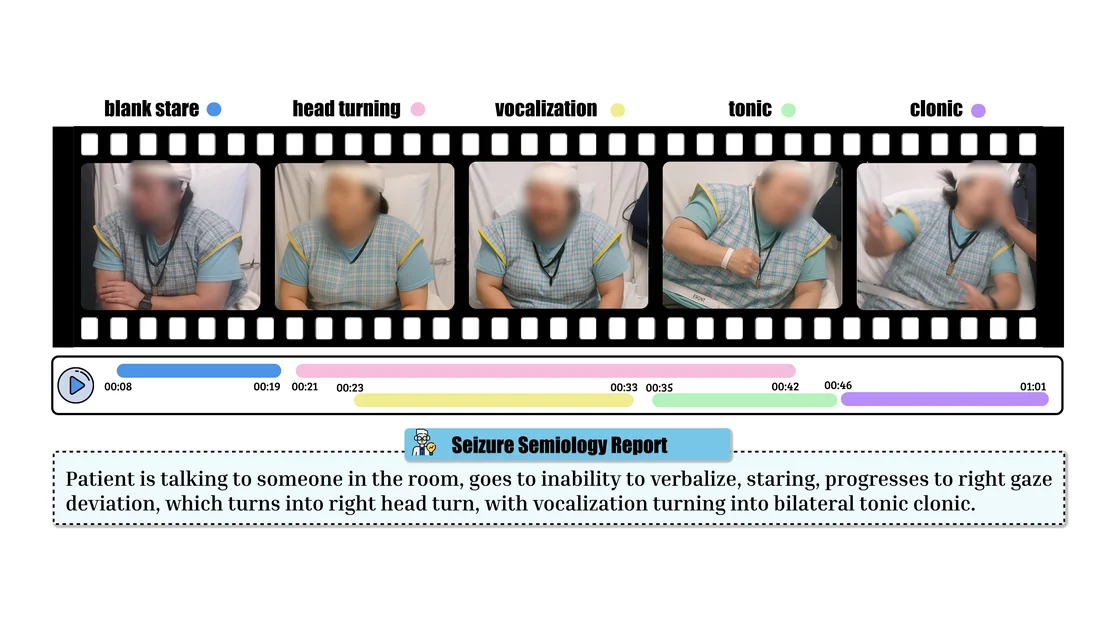
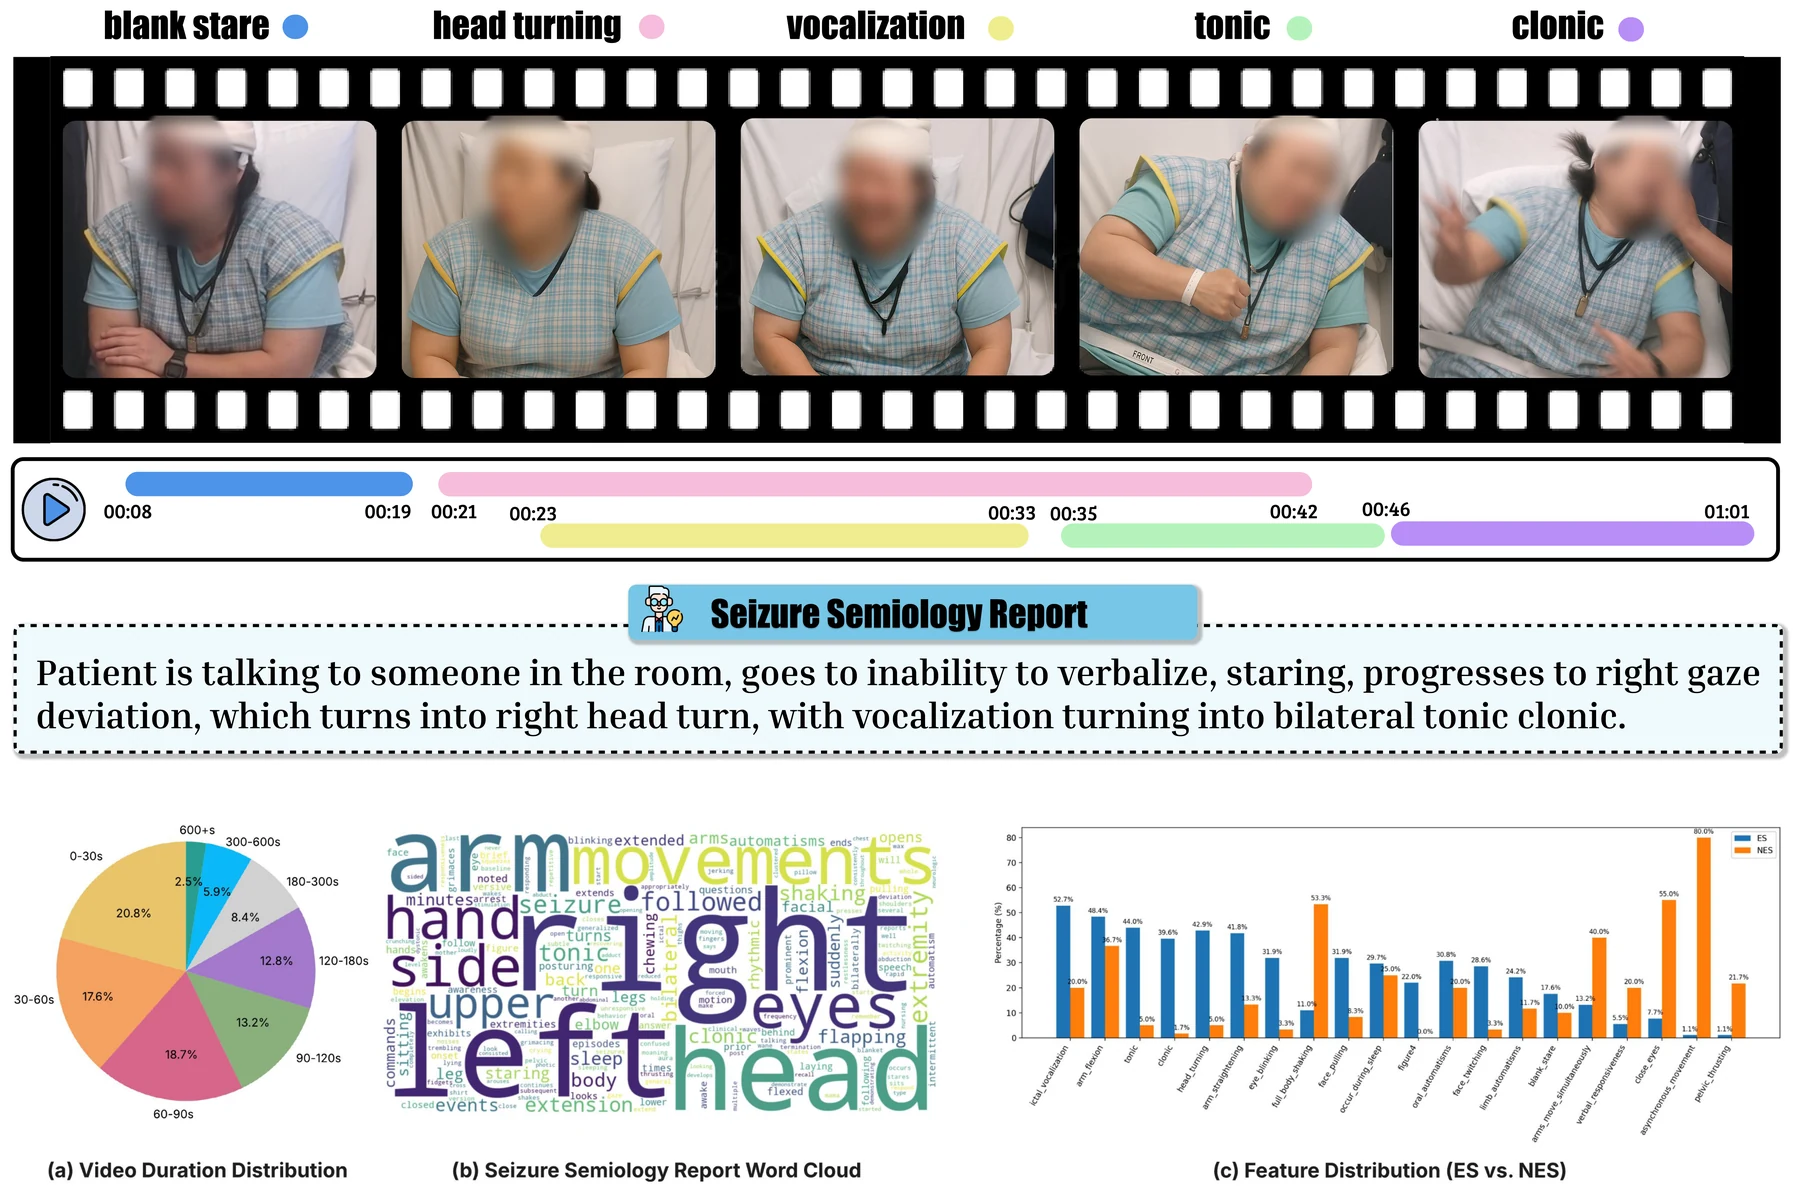
Seizure-Semiology-Suite (S3)
I built a clinical seizure-semiology dataset and served three vision-language models with vLLM for the S3 benchmark.
ICML 2026 Spotlight Paper
-
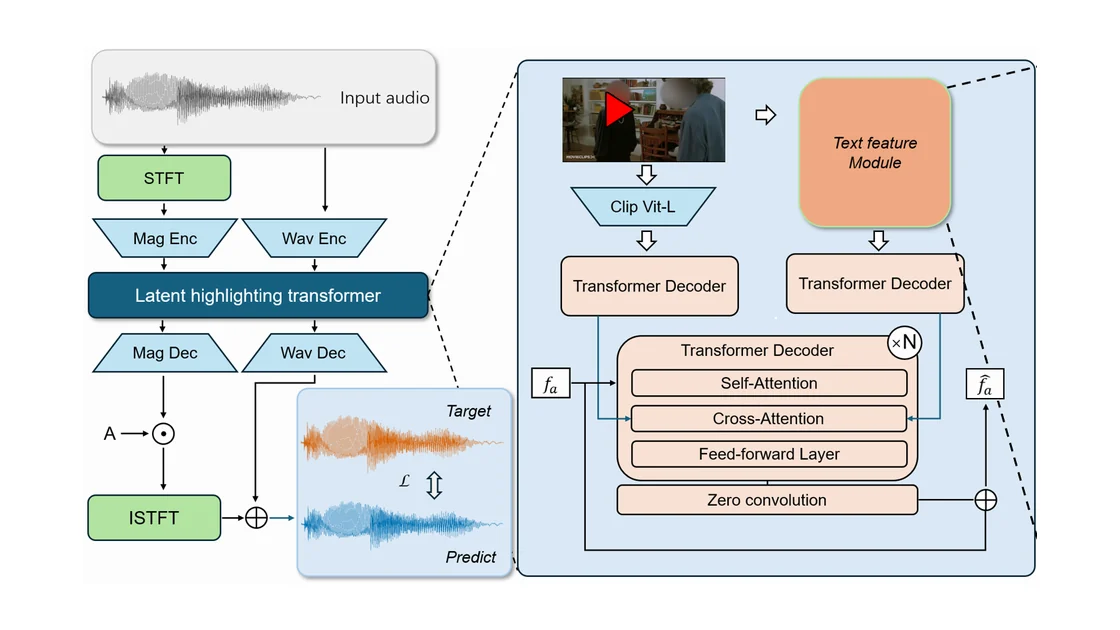
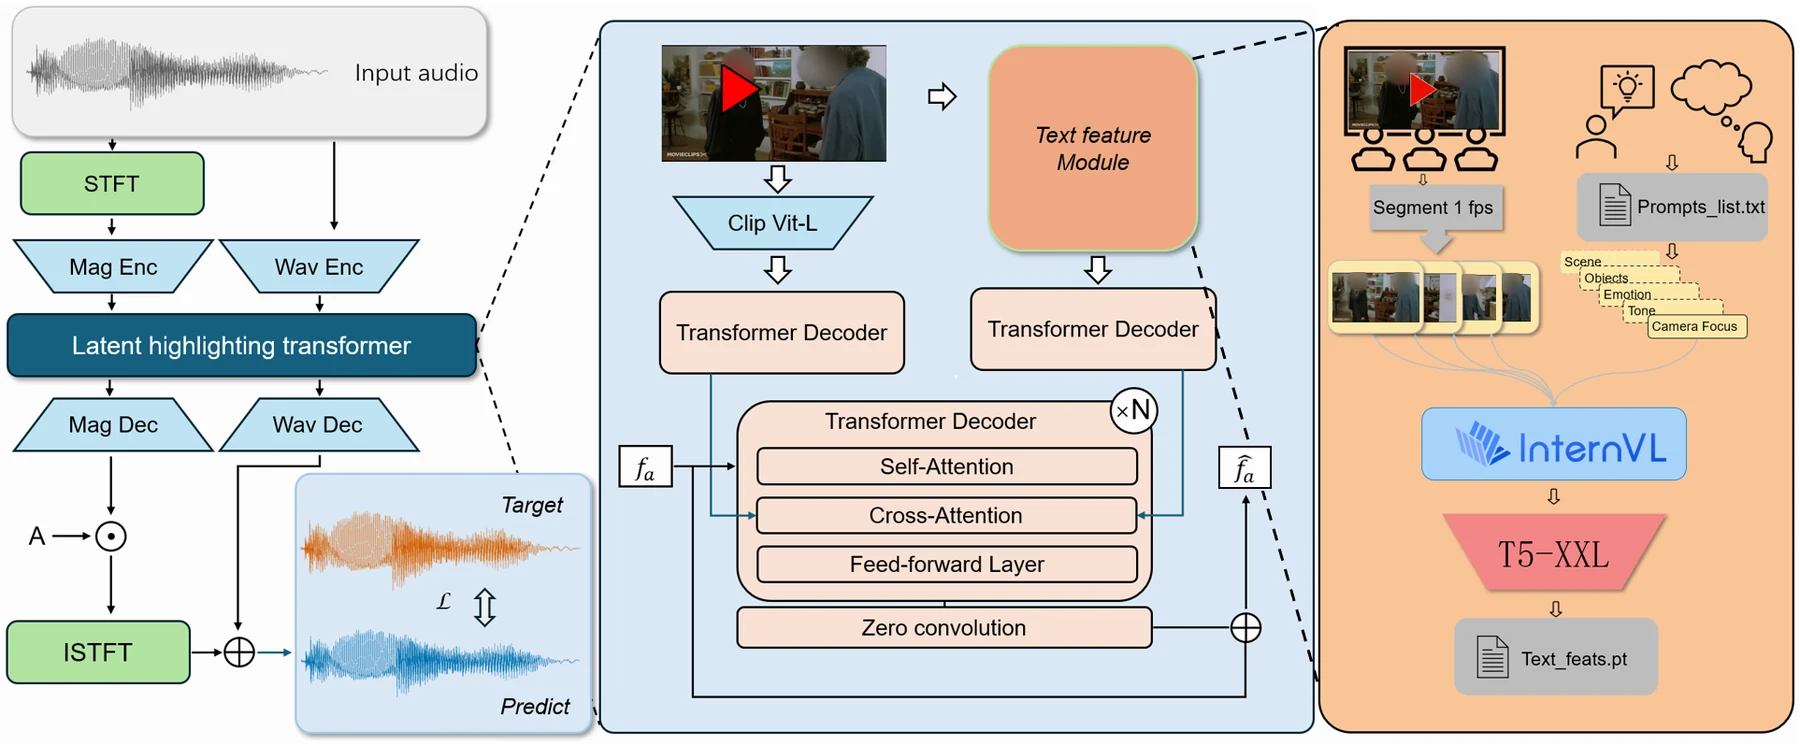
Acoustic highlighting & co-speech gestures
I'm first author of a paper on vision-language-guided acoustic highlighting. Before that, I worked on co-speech gesture generation for GestureLSM.
-
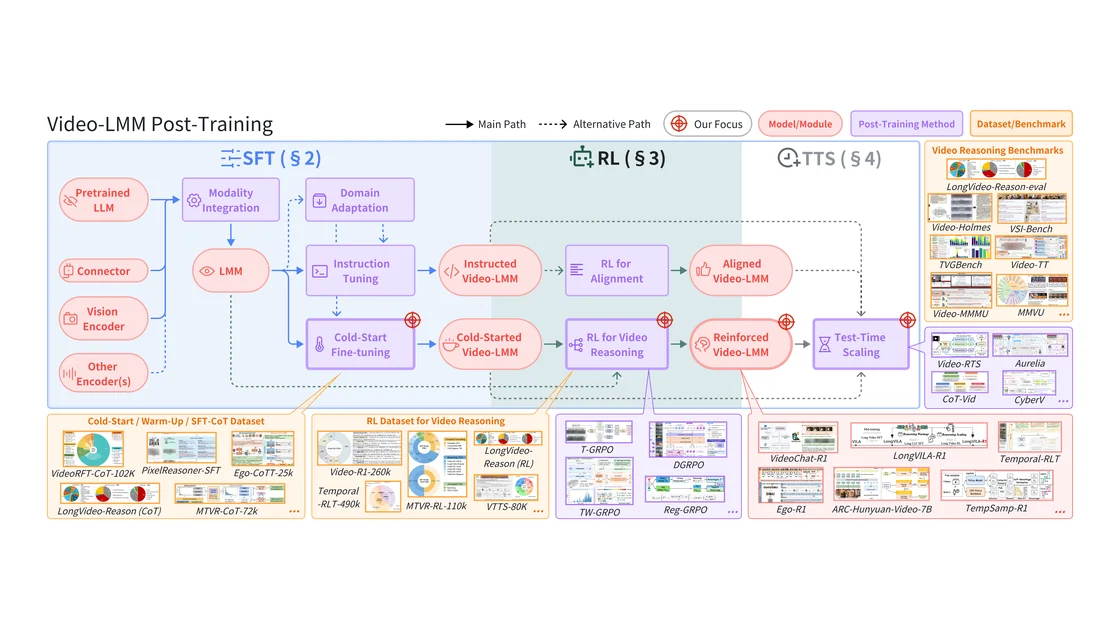
Skeleton-to-image & Video-LMM survey
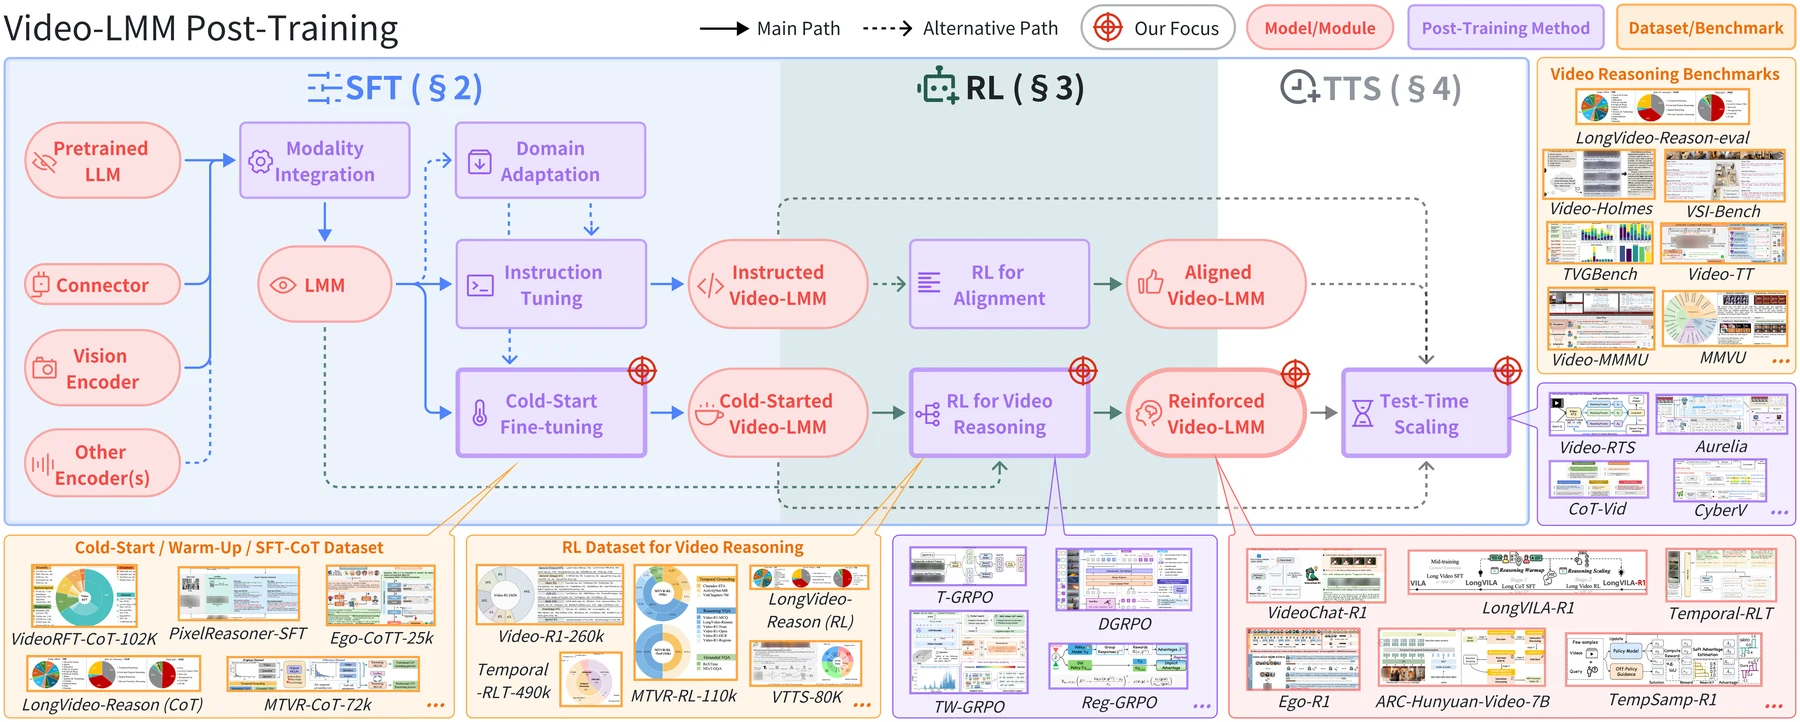
I generated animal images from skeletons with Stable Diffusion and preference optimization. I also contributed to a survey on Video-LMM post-training.
-
City-scale Gaussian Splatting
I cut down floating artifacts in city-scale reconstructions with incidence-angle weighting and depth/normal supervision, and split the preprocessing across machines.
Papers
All publications-
Under submission
ChairNav: Cross-Embodiment Pre-training and Personalization for Long-Horizon Wheelchair Navigation
-
CoRL 2026
Cue the Flow: Steering Flow-Matching Policies for Open-World Delivery Manipulation
-
Findings of EMNLP 2026
ToolSmith: An Automatic Tool-Generation Framework for Multimodal Search Agents
-
ICML 2026 Spotlight
Seizure-Semiology-Suite (S3): A Clinically Multimodal Dataset, Benchmark, and Models for Seizure Semiology Understanding
-
ICCV 2025
GestureLSM: Latent Shortcut based Co-Speech Gesture Generation with Spatial-Temporal Modeling
-
arXiv 2026
Semantic Visually-Guided Acoustic Highlighting with Large Vision-Language Models
-
arXiv 2026
GestureFAR: Streaming Co-Speech Gesture Generation with Flow Autoregression
* Equal contribution.
Education
Full CV- University of California, Los Angeles M.S. Electrical and Computer Engineering Expected 2027
- University of Rochester B.S. Computer Science & B.S. Business · GPA 3.82 May 2025